Auditing One Collection: A Quick-Start Guide
cmr-quickstart.RmdThis is the narrow path: you have one collection (or a rough idea of
one) and you want to know when its files actually change. If you’re
curious about the broader exploration that shaped this package’s other
functions – collection discovery, S3 region gotchas, provider-specific
metadata quirks – see vignette("cmr-landscape") instead.
This article sticks to the five steps that matter for a single
collection.
Step 1: find your collection
If you already have a short_name, skip to Step 2.
Otherwise, cmr_find_collections() does a free-text search
across CMR’s collection metadata (title, abstract, science keywords,
platforms, instruments, …):
cmr_find_collections(keyword = "sea surface temperature", provider = "POCLOUD",
                      page_size = 5, granule_count = FALSE) |>
  dplyr::select(short_name, entry_title, provider, version)
#> 5 of 499 total matching collections returned (page 1) -- raise `page_size` (CMR max 2000), narrow `keyword`/`provider`, or use cmr_all_collections() to see more.
#> # A tibble: 5 × 4
#>   short_name                  entry_title                       provider version
#>   <chr>                       <chr>                             <chr>    <chr>
#> 1 OSTIA-UKMO-L4-GLOB-REP-v2.0 GHRSST Level 4 OSTIA Global Hist… POCLOUD  2.0
#> 2 MUR-JPL-L4-GLOB-v4.1        GHRSST Level 4 MUR Global Founda… POCLOUD  4.1
#> 3 MUR25-JPL-L4-GLOB-v04.2     GHRSST Level 4 MUR 0.25deg Globa… POCLOUD  4.2
#> 4 MODIS_T-JPL-L2P-v2019.0     GHRSST Level 2P Global Sea Surfa… POCLOUD  2019.0
#> 5 OSTIA-UKMO-L4-GLOB-v2.0     GHRSST Level 4 OSTIA Global Foun… POCLOUD  2.0
This example uses this vignette’s running example throughout:
MUR-JPL-L4-GLOB-v4.1, GHRSST’s daily global
sea-surface-temperature analysis.
Step 2: is it actually alive, and what does it cover?
Before auditing anything, two quick sanity checks. First, the collection’s own declared metadata:
cmr_find_collections(short_name = "MUR-JPL-L4-GLOB-v4.1") |>
  dplyr::select(temporal_start, temporal_end, ends_at_present, granule_count)
#> # A tibble: 1 × 4
#>   temporal_start           temporal_end ends_at_present granule_count
#>   <chr>                    <chr>        <lgl>                   <int>
#> 1 2002-05-31T21:00:00.000Z NA           FALSE                    8858
granule_count > 0 confirms this collection actually
has UMM-G granules to audit at all – some CMR “collections” don’t (see
vignette("cmr-landscape")’s AADC example).
temporal_start is usually reliable;
ends_at_present/temporal_end are declared
metadata that vary a lot in reliability by provider, so don’t lean on
them alone –
cmr_collection_liveness("MUR-JPL-L4-GLOB-v4.1")
#> # A tibble: 1 × 5
#>   short_name           provider lookback_days recent_granule_count is_live
#>   <chr>                <chr>            <dbl>                <int> <lgl>
#> 1 MUR-JPL-L4-GLOB-v4.1 NA                  60                   59 TRUE
cmr_collection_liveness() checks real granule activity
in a recent window directly, which is the more trustworthy “is this
still going” signal. recent_granule_count capped at your
page_size (default 2000) just means “at least that many” –
raise lookback_days for low-cadence collections (annual
composites, etc.) that might show is_live = FALSE over a
short window despite being fine.
Step 3: run the audit
cmr_audit_revisions() sweeps a date range in 3-month
chunks and returns one row per granule, with the full
revision/production lifecycle. This example covers a little over a year
to keep the vignette quick to build; drop from further back
for a fuller picture (MUR itself goes back to 2002):
rev <- cmr_audit_revisions("MUR-JPL-L4-GLOB-v4.1", from = Sys.Date() - 400)
#> 2025-07-29 .. 2025-10-28 : 93 granules
#> 2025-10-29 .. 2026-01-28 : 93 granules
#> 2026-01-29 .. 2026-04-28 : 91 granules
#> 2026-04-29 .. 2026-07-28 : 92 granules
#> 2026-07-29 .. 2026-09-02 : 34 granules
rev |>
  dplyr::select(gran_date, n_rev, insert_date, update_date, production,
                prod_lag) |>
  head()
#> # A tibble: 6 × 6
#>   gran_date  n_rev insert_date              update_date      production prod_lag
#>   <date>     <int> <chr>                    <chr>            <chr>         <dbl>
#> 1 2025-07-29    18 2025-08-07T07:52:43.073Z 2025-08-07T07:5… 2025-08-0…        9
#> 2 2025-07-30    18 2025-08-08T07:52:42.035Z 2025-08-08T07:5… 2025-08-0…        9
#> 3 2025-07-31    18 2025-08-09T07:52:29.727Z 2025-08-09T07:5… 2025-08-0…        9
#> 4 2025-08-01    18 2025-08-10T07:52:31.186Z 2025-08-10T07:5… 2025-08-1…        9
#> 5 2025-08-02    18 2025-08-11T07:52:29.352Z 2025-08-11T07:5… 2025-08-1…        9
#> 6 2025-08-03    18 2025-08-12T07:51:33.427Z 2025-08-12T07:5… 2025-08-1…        9
The column dictionary, briefly (full detail in the README):
| column | what it tells you |
|---|---|
n_rev |
how many times the CMR metadata record was touched – often bulk provider events, not evidence the file changed |
insert_date/update_date
|
UMM ProviderDates – first publish / latest metadata
touch |
production |
DataGranule.ProductionDateTime – when the science file
itself was generated. This is the churn-immune
signal
|
*_lag |
each date above minus gran_date, in days |
range(rev$n_rev)
#> [1]  2 22
If that range is wide (as it typically is for actively-maintained
GHRSST products), don’t read it as “this file was regenerated that many
times” – cross-check against prod_lag instead, which is
immune to metadata churn.
Step 4: look at it
plot_cmr_lifecycle(rev)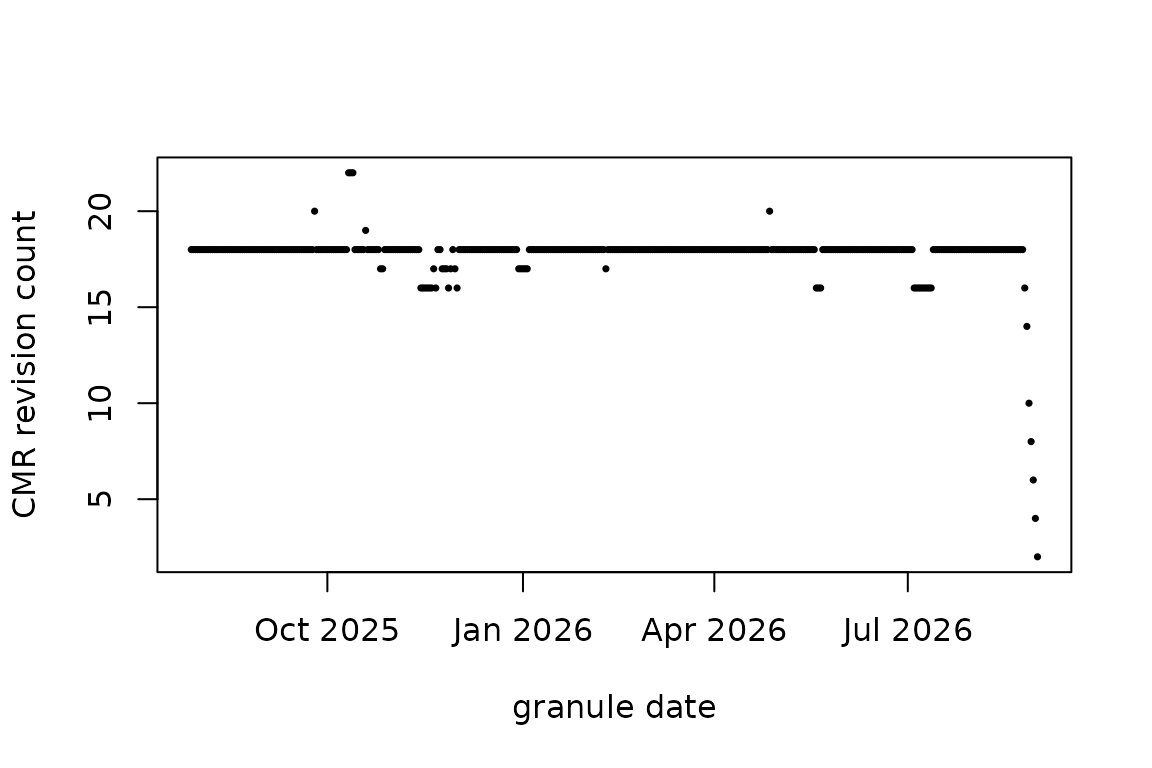
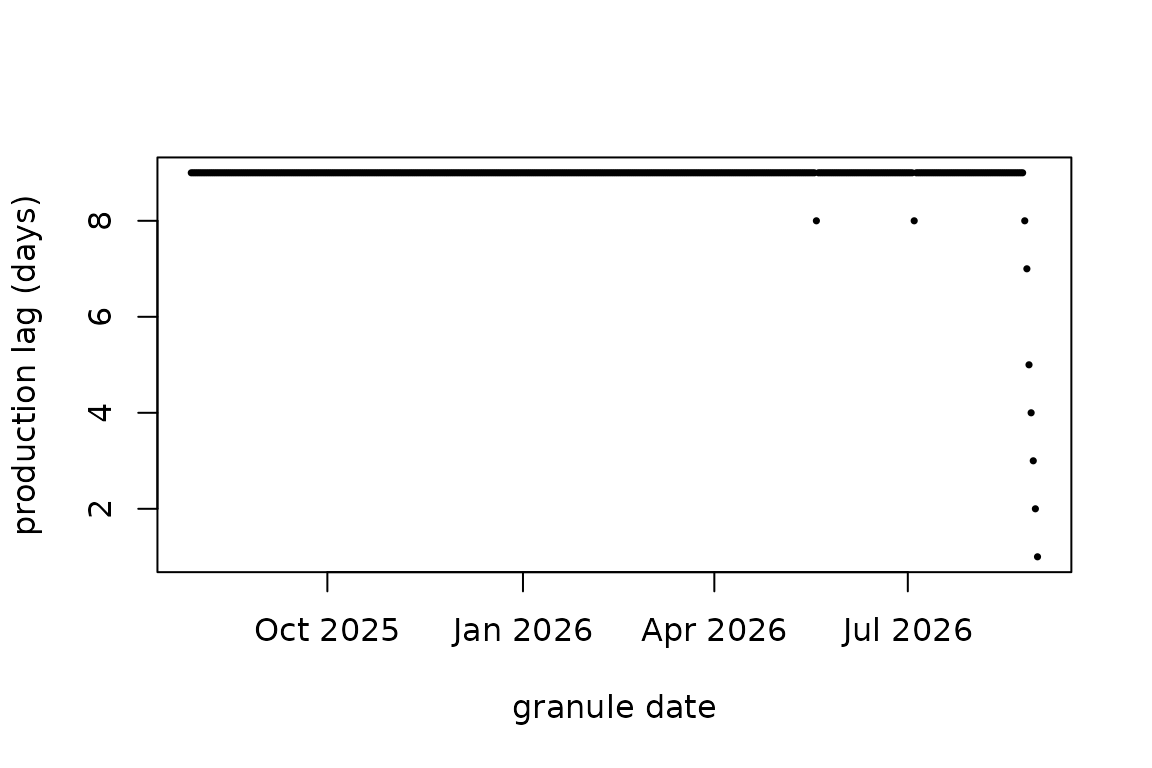
Two things to look for:
-
Revision count vs. granule date (top plot): a
staircase pattern (roughly constant counts jumping at specific dates
across many granules) usually means
n_revis tracking a bulk metadata event, not per-granule data changes. - Production lag vs. granule date (bottom plot): expect a flat band at a stable finalization lag for settled/older dates, with smaller lags only at the frontier (recent dates still on a near-real-time product, not yet replaced by the finalized file).
When your collection doesn’t play by MUR’s rules
Two things assumed above don’t hold universally:
Opaque GranuleUR, no embedded date.
gran_date defaults to parsing a leading
YYYYMMDD out of granule_ur – true for
GHRSST-style products, not universal. Some collections (e.g. MODIS swath
products via LAADS) use an opaque GranuleUR like
"LAADS:9975745835". cmr_audit_revisions()
warns (not errors) if gran_date comes back entirely
NA; the fix is to derive it from
temporal_start instead:
rev_swath <- cmr_audit_revisions("MOD021KM",
  from = as.Date("2026-08-01"), to = as.Date("2026-08-02"),
  gran_date_fun = function(df) as.Date(df$temporal_start))
Too many granules worldwide. Swath products can
produce hundreds of granules a day globally.
cmr_find_granules()/cmr_audit_revisions() take
an optional bounding_box
(c(west, south, east, north)) or polygon
filter to subset to a region of interest instead:
cmr_find_granules("MOD021KM", as.Date("2026-08-01"), as.Date("2026-08-01"),
                   bounding_box = c(140, -45, 155, -35))
If your collection is cloud-hosted
Check region/s3_credentials_endpoint before
relying on s3_url for compute placement –
s3:// links are only cheap from matching-region compute,
and require an Earthdata Login credential exchange regardless of
region:
cmr_find_collections(short_name = "MUR-JPL-L4-GLOB-v4.1") |>
  dplyr::select(region, s3_credentials_endpoint)
#> # A tibble: 1 × 2
#>   region    s3_credentials_endpoint
#>   <chr>     <chr>
#> 1 us-west-2 https://archive.podaac.earthdata.nasa.gov/s3credentials
vignette("cmr-landscape") covers why this matters in
more detail.
Cheat sheet
library(cmrlifecycle)

# 1. find it (skip if you know short_name)
cmr_find_collections(keyword = "...")

# 2. sanity check
cmr_collection_liveness("your-short-name")
cmr_find_collections(short_name = "your-short-name")

# 3. audit
rev <- cmr_audit_revisions("your-short-name", from = as.Date("2024-01-01"))

# 4. look
plot_cmr_lifecycle(rev)

# only if needed:
# - opaque GranuleUR:  gran_date_fun = function(df) as.Date(df$temporal_start)
# - swath volume:      bounding_box = c(west, south, east, north)
# - cloud compute:     check region / s3_credentials_endpoint first